

ITOM vs. ITSM is a decision about two connected responsibilities: keeping technology running and delivering dependable IT services to the people using it. An operations team may detect rising database latency before anyone complains, while a service desk manages the resulting disruption and keeps affected users informed.
CIOs, IT managers, NOC leaders, and managed service providers need to understand where these functions differ, which measures apply to each, and how their handoff works when a critical service fails.
ITOM vs. ITSM: The Short Answer
ITSM manages how IT services are delivered, restored, and improved for users. ITOM manages the availability, health, and performance of the infrastructure behind those services. ITSM starts with service commitments and user needs; ITOM works with technical events and operational data. Organizations use both when infrastructure issues must lead to coordinated service restoration.
What ITSM and ITOM Each Cover
ITSM: Managing Service Delivery for Users
IT Service Management coordinates how employees and customers request services, report interruptions, and receive updates. It establishes ownership, priorities, approvals, and service commitments, giving the service desk a consistent way to handle work from intake through closure. Its primary view is the service experienced by the user.
Core ITSM Practices
- Incident Management restores disrupted services and records the response
- Change Enablement assesses proposed changes, associated risks, and approval decisions
- Problem Management investigates recurring incidents and underlying causes
- Service request management handles routine access, information, and provisioning requests
ITOM: Managing Infrastructure Health and Performance
IT operations management covers the daily monitoring and management of networks, servers, applications, and cloud resources. Operations teams examine performance conditions and system dependencies to detect faults and identify where technical intervention is needed. Their immediate concern is the condition of the technology delivering the service.
Core ITOM Capabilities
- Infrastructure monitoring tracks availability, latency, capacity, and resource utilization
- Event and alert management groups related signals and prioritizes conditions that warrant investigation
- Discovery and dependency mapping connects components to the applications and business services relying on them
- Root cause analysis examines metrics, events, and relationships to narrow the source of a failure
Organizations comparing infrastructure monitoring products should assess the discovery coverage, event handling, and diagnostic information available through IT operations management tools.
ITSM vs. ITOM: Key Differences Compared
| Dimension | ITSM | ITOM |
|---|---|---|
| Main responsibility | Deliver and restore services for users | Maintain infrastructure health and performance |
| Primary audience | Service desk, service owners, business users | NOC staff, infrastructure engineers, operations leads |
| Typical trigger | User report, service request, SLA breach risk | Threshold breach, performance anomaly, device event |
| Working data | Tickets, approvals, service catalog, user feedback | Metrics, logs, events, topology, dependency information |
| Typical action | Categorize, assign, escalate, communicate, close | Detect, correlate, diagnose, remediate, verify |
| Success measures | SLA attainment, first-contact resolution, CSAT | Uptime, MTTD, alert quality, resource performance |
| ITIL 4 practices | Incident, request, problem, change and service level practices; see ITIL vs. ITSM | Monitoring and event management with operational contributions to incident, change and configuration work |
| Main question | How quickly was the affected service restored for the user? | What failed, why, and which systems are affected? |
Focus and Audience
The distinction becomes clearer during a payroll application outage. The service desk receives employee complaints, identifies their impact, assigns severity, and coordinates communication. Operations personnel investigate the application server, network path, or database component responsible for the interruption. Both groups contribute to restoration, but they start from different information and answer to different service outcomes.
The same separation applies during routine work. ITSM handles an approved request for access to a business system; ITOM checks the capacity and availability of the systems needed to deliver that access. Shared priorities still leave each function with distinct responsibilities.
Consider an organization operating a customer portal and an internal finance system. The finance service owner may classify a short disruption as high priority near payroll cutoff, even when the underlying server metrics appear normal. Conversely, an operations engineer may flag sustained storage growth as an urgent infrastructure concern days before users experience delays. Those priorities can both be reasonable. ITSM establishes the user-facing importance of the issue, while ITOM provides evidence about technical exposure and recovery options.
Responsibility also differs after restoration. Service management confirms that affected users can resume work, records communication, and checks incident closure requirements. Operations reviews component stability and recurring technical indicators. A closed ticket and a healthy device are separate checks; relying on either alone can conceal an incomplete recovery.
Data Sources and Triggers
ITSM work typically enters through portals, email, service catalogs, and agent-created tickets. Requests arrive with information about the requester, urgency, affected service, and required approval. These details help teams decide ownership and communicate progress.
ITOM receives telemetry generated by devices and applications. A sudden increase in response time, rising disk utilization, or a failed network interface may trigger an alert before any user reports an issue. A monitoring event becomes a service incident when it affects, or threatens to affect, a service that someone relies on.
An alert threshold also carries a different meaning from a service priority. CPU utilization above an agreed limit can trigger investigation, yet the assigned incident severity depends on the service affected, duration, and business timing. Multiple technical events may correspond to one interruption. Equally, one incident may involve several affected services when a shared dependency fails.
Teams should decide which event attributes transfer into an incident record: affected configuration item, first observed time, current status, suspected dependency, and links to related alerts. Requester details and business impact may need to be added by the service desk. These fields help prevent engineers and agents from running separate investigations using incomplete timelines.
Success Metrics: SLA and CSAT vs. Uptime and MTTD
ITSM teams track service level agreement attainment, customer satisfaction (CSAT), ticket backlog, and restoration times. ITSM metrics reveal delays in intake, assignment, approvals, and communication, as well as resolution performance.
ITOM measures uptime, mean time to detect (MTTD), event volume, and time spent diagnosing faults. Mean time to resolve or restore (MTTR) matters to both groups, although each can contribute a different segment of that interval. A monitoring alert discovered within seconds offers limited business value if the service desk learns about the impact much later.
Metric interpretation requires shared timestamps and clear definitions. MTTD may be measured from the beginning of a detectable fault to the first alert, while an SLA response clock can start when a ticket is accepted or submitted under the agreed policy. Comparing the two figures without their starting points creates misleading reporting. Teams should document which intervals they own and which pauses or exclusions apply.
A monthly review can then separate four questions: Was the problem detected early? Did the relevant team receive it quickly? How long did repair take? When did users confirm restoration? Answering each question independently exposes stalled handoffs that a single end-to-end average can hide.
Where ITSM and ITOM Overlap
ITSM and ITOM both depend on reliable service information, coordinated change activity, and clear incident ownership. They may work in separate systems, yet an outage often requires people from both teams to review the same technical history and business impact. Their overlapping work is most visible during high-severity incidents and changes affecting production systems.
Shared Practices: Change and Configuration
A network upgrade illustrates the overlap. Service management records the planned change, risk assessment, approvals, and communication schedule. Operations evaluates device health, dependencies, maintenance windows, and rollback conditions. When execution finishes, the service team checks the service outcome while engineers verify technical stability.
Configuration data adds another connection. If a switch replacement changes application connectivity, service teams need to know which services were affected. Engineers need an accurate change record to determine if the recent work explains a new alert.
A Shared CMDB and Service Context
A Configuration Management Database (CMDB) records configuration items and relationships among services, applications, and infrastructure components. When an ITOM alert identifies a failed database host, service context can reveal which customer-facing applications depend on it. That information helps the service desk set incident priority and communicate the likely impact.
The CMDB must have current relationships to remain useful. Stale component ownership or missing dependencies can send responders down the wrong path. Discovery updates and change records therefore need defined responsibility rather than occasional manual reconciliation.
Service relationships also help during planned maintenance. If a database cluster serves three applications, operations can identify the components under maintenance while service management determines which business units need advance communication. An accurate dependency record can reveal shared risk even when individual infrastructure devices report healthy status.
Configuration governance becomes harder in hybrid environments. A cloud instance may be replaced automatically, while a branch router remains in place for years. Both can appear in an incident history, but their identifiers, ownership fields, and update frequency differ. A useful CMDB links these records to persistent service identities and assigns someone to investigate missing or conflicting relationships before an outage makes them urgent.
ITOM vs. ITSM vs. AIOps: Where AI Fits
AIOps connects operational signals with service workflows through analytics and automation, while ITOM and ITSM retain their separate responsibilities.
AIOps on the ITOM Side
During a major network incident, dozens of interfaces and connected applications may produce alerts for the same underlying failure. Event correlation groups related signals, reducing duplicate investigations and exposing the probable point of failure. Trend analysis can flag worsening capacity or recurring anomalies early enough for engineers to assess the risk of disruption.
Predictions still need operational judgment. A forecast of exhausted storage has value only when it considers the workload, maintenance schedule, and possible impact on the service.
Alert correlation should also preserve the evidence behind its recommendation. A shared switch failure might generate alerts from connected servers and an application, yet the initial trigger and dependency information should remain available for investigation. An engineer needs to distinguish an inferred cause from a verified one, especially before restarting infrastructure or changing production configurations.
Teams can assess the value of analytics by examining the proportion of correlated events that led to actionable cases, the time required to validate probable causes, and the number of incidents identified before user reports. An impressive reduction in alert volume means little if critical warnings disappear with the noise.
AIOps on the ITSM Side
When monitoring identifies an actionable issue, automation can create a ticket with the affected configuration item and correlated events attached. Assignment rules then use service ownership, severity, and team availability to route the case. This shortens the interval between detection and a person taking responsibility for restoration.
AI in ITSM can also recommend related knowledge records and previous fixes. Human responders still verify the diagnosis and authorize high-risk actions. Lower MTTR depends on the quality of the underlying data and the handoff, rather than automation alone.
ITOM vs. ITSM Examples: How They Work Together in Practice
From Alert to Resolved Ticket: The Handoff
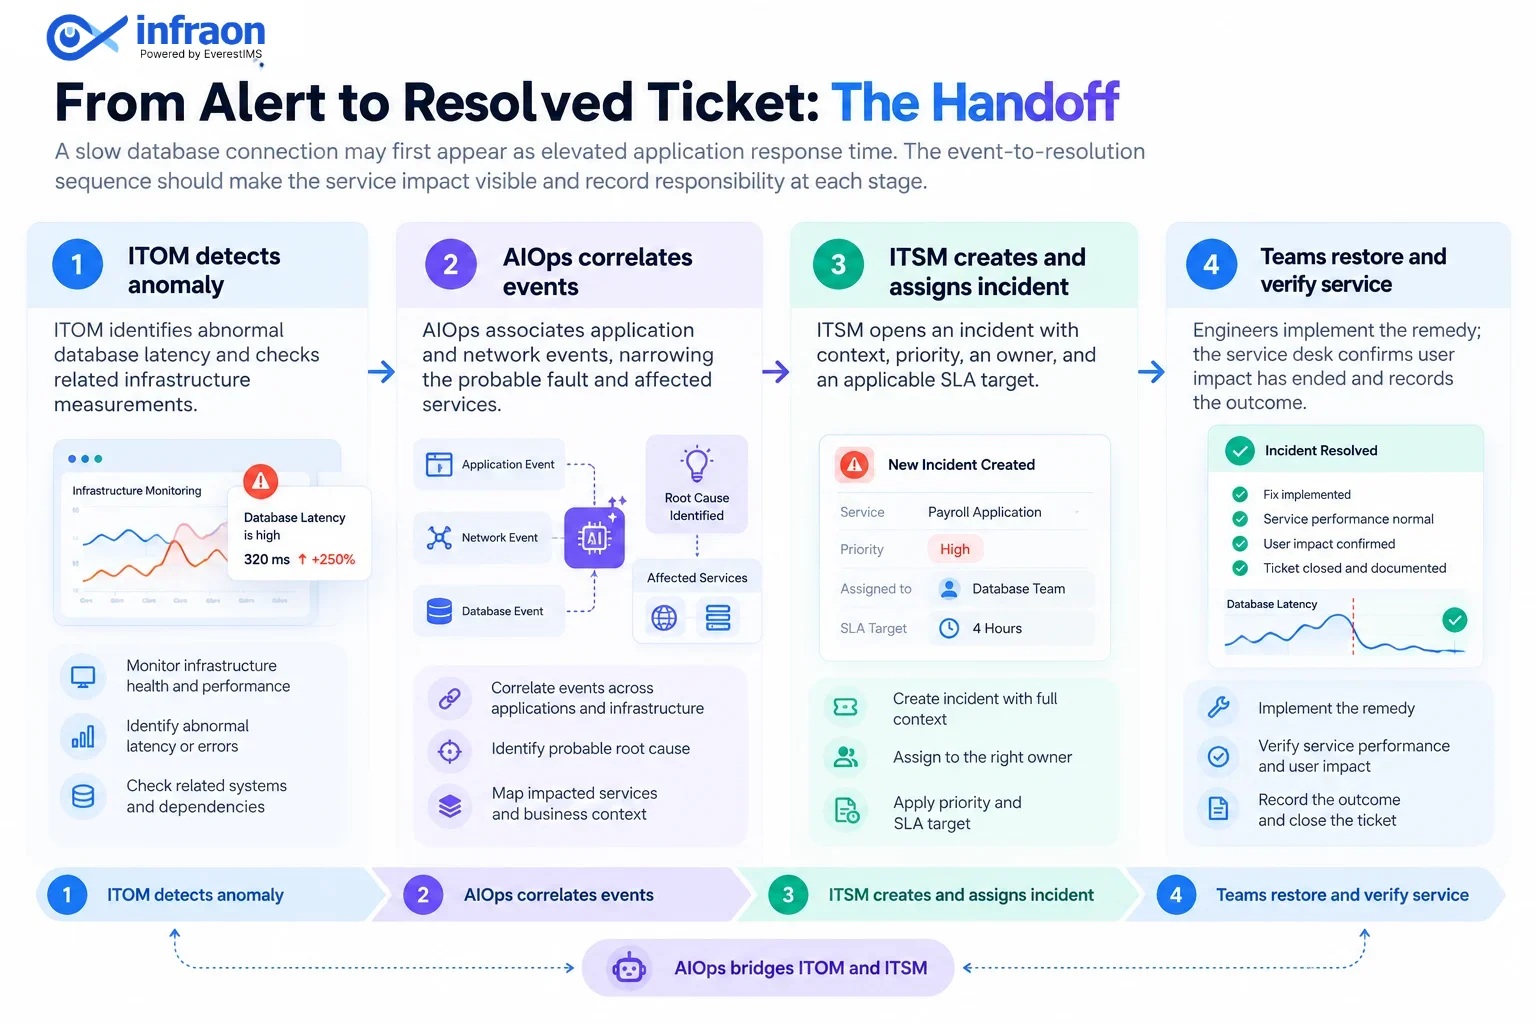
A slow database connection may first appear as elevated application response time. The event-to-resolution sequence should make the service impact visible and record responsibility at each stage.
- Detect: ITOM identifies abnormal database latency and checks related infrastructure measurements
- Correlate: AIOps associates application and network events, narrowing the probable fault and affected services
- Create and assign: ITSM opens an incident with context, priority, an owner, and an applicable SLA target
- Restore and verify: Engineers implement the remedy; the service desk confirms user impact has ended and records the outcome
A clear handoff prevents duplicate investigations. It also produces an incident record that includes discovery, diagnosis, work performed, communication, and closure evidence.
The transfer should contain enough context for the receiving team to act without searching through every monitoring console. A ticket can carry the first and latest alert times, impacted service, correlated event group, suspected component, recent change history, and a link to the live operational record. The service desk then adds user impact, contractual priority, assigned resolver group, and the next communication time.
Reassignment deserves the same attention as creation. If network engineers determine that the issue lies in the database layer, the incident should retain previous findings rather than start again with an empty description. After technical recovery, an application owner or representative user can confirm the service outcome. Repeat incidents should be linked to problem investigation when temporary recovery leaves the underlying cause unresolved.
Real-World Use Cases
E-commerce Flash-Sale Slowdown
A retailer’s checkout pages respond slowly during a short promotional surge. ITOM detects rising application latency and network congestion; correlation helps engineers distinguish demand-driven saturation from an unrelated device fault. ITSM raises the incident priority according to affected transactions, assigns the responsible team, and coordinates updates to the business. Once capacity or routing is adjusted, the service desk verifies that checkout times have recovered before closure.
During investigation, technical teams compare current traffic with the normal promotional baseline and check if the slowdown affects browsing, payment authorization, or order submission. This distinction changes the service priority: slow product images and failed payments have different commercial consequences.
Customer service teams need an agreed statement about the affected checkout stage and the expected next update, even while engineering work continues.
Manufacturing Line Downtime
A production cell loses connectivity to a supervisory control system. Operations monitoring identifies a failing switch and maps which connected systems may be affected. ITSM opens a high-priority incident, records the plant’s operational impact, and tracks dispatch and replacement work. The handoff matters because restoring the device alone cannot confirm the production service is available again; plant personnel must validate the result.
That verification may involve checking if equipment telemetry has resumed, confirming that queued production instructions were handled correctly, and assessing the need to inspect incomplete batches. Service management keeps the restoration record aligned with the plant’s operational decision.
ITOM retains the technical evidence needed to explain why a switch, link, or connected control component failed and if similar units show related warning signs.
MSP Managing Multiple Clients
A managed service provider handles alerts from several customer environments, each with a distinct contract and escalation window. ITOM groups infrastructure signals by environment, then correlation reduces repeated alerts from a shared fault. ITSM creates customer-specific incidents with the correct service targets and assignment rules. Separate reporting shows each customer what happened and how the incident was handled without mixing their operational records.
The provider also needs rules for shared tooling. A common monitoring engine may serve several customers, but incident visibility, access permissions, response targets, and reporting must remain separated. If a supplier outage affects multiple environments, engineers may investigate one technical event while customer-facing teams manage distinct service commitments.
This avoids duplicating diagnosis while preserving the correct communication and resolution history for each contract.
ITSM or ITOM First? A Decision Guide
Start With ITSM If Tickets Are the Bottleneck
Prioritize service management when requests sit unanswered, escalations lack owners, or users receive inconsistent updates. Kick off with incident categories, a clear assignment model, service targets, and a small set of repeatable request workflows. Review backlog age and SLA misses after rollout. This sequence tackles the problems employees already experience, even when infrastructure monitoring remains basic.
A useful starting assessment compares ticket arrival rates with completed work and identifies where requests remain idle. Long waits before assignment call for different action from repeated escalations after assignment. Review a representative sample of unresolved tickets to identify unclear categories, absent approvers, and handoffs between groups. The initial rollout can focus on the two or three request types responsible for the largest recurring backlog, with results checked against the original volume.
Start With ITOM If Outages Arrive Unannounced
Prioritize operations visibility when services fail before engineers see any warning, or incident diagnosis requires searching several disconnected consoles. Map critical systems, define useful monitoring thresholds, and establish escalation paths for high-impact alerts. Measure detection time and the ratio of actionable alerts to noise. A monitoring deployment should identify the failures that threaten service availability rather than simply generate high event volume.
Get started with a service inventory rather than a device count. Identify the applications whose failure would interrupt transactions, employee access, or production, and record the infrastructure dependencies that can be monitored. Establish escalation thresholds for those services and test if alerts reach an accountable responder during evenings and weekends. Early monitoring success is measured through actionable detection and timely investigation, rather than the number of new dashboards.
Run Both When Scale and Uptime Matter
Organizations managing business-critical applications, dispersed sites, or round-the-clock services often need coordinated service and operations management. Begin by linking a few critical monitored services to incident workflows, then extend the model based on observed results. An integrated ITSM and ITOM setup can connect event context, incident ownership, escalation, and recovery records.
The adoption order can differ by organization. The shared outcome is a shorter path from detecting a technical fault to restoring the service that people use.
Some enterprises already have mature incident workflows but weak visibility into network dependencies. Others run extensive monitoring while their service desk relies on email threads. The first investment should address the larger operational exposure. After that, connect the disciplines around one business service and record how quickly an alert becomes an owned incident. Review missed alerts, duplicate tickets, delayed escalations, and user confirmation before extending the connection to other services.
Common Myths about ITOM vs. ITSM
“ITOM Replaces ITSM”
Monitoring may reveal a failing component, but it cannot settle every approval, communicate service updates, or manage the user’s restoration experience. Likewise, a well-run service desk cannot infer infrastructure health from tickets alone. Each discipline fills an operational gap that remains when the other is deployed independently.
“ITOM and AIOps Are Only for Large Enterprises”
Smaller teams can gain value from alert consolidation and earlier fault detection when they run critical services with limited engineering cover. The starting scope may be a few key applications rather than an enterprise-wide monitoring estate. Analytics should follow a measurable problem, such as repeated false alarms or missed capacity warnings.
How Infraon Brings ITSM and ITOM Together
Infraon connects service records with infrastructure information through its wider IT management offering. The ITSM tool handles incidents, requests, service targets, assignments, and approvals, while Infraon Infinity brings operational monitoring, discovery, and analytics into the same service context. An event identified by monitoring can enter an incident workflow with information about the affected asset and service, reducing the need to reconstruct the fault history manually.
Operations engineers can work from alert and dependency information while service teams track ownership, escalation, and user communication. This combination is useful for organizations seeking one record of the incident from detection through restoration. Teams can establish the initial connection around critical services, review alert quality and ticket outcomes, and extend coverage as operating needs grow.
Frequently Asked Questions
Is ITOM part of ITSM?
ITOM and ITSM are related IT management disciplines with different responsibilities. ITOM concentrates on the technology operating behind services, while ITSM governs delivery and restoration from the user’s perspective. Their practices intersect during incidents, changes, and configuration updates.
Can ITSM work without ITOM?
Yes. A service desk can manage requests, incidents, and approvals using basic infrastructure visibility. As technical complexity rises, missing monitoring context can slow detection and diagnosis. The need for ITOM depends on the services an organization runs and the risk of failures going unseen.
What is the difference between ITSM, ITOM and ITAM?
ITSM manages service delivery, ITOM manages operating conditions, and IT asset management manages technology assets and their lifecycle. ITAM records can enrich both operations and service work.
Also read:
Is ITOM only for enterprises?
No. A small organization running revenue-critical applications may need monitoring just as urgently as a large enterprise. The difference lies in the number of systems, desired coverage, and the team’s capacity to respond to alerts.
Does AIOps replace IT operations teams?
No. AIOps can group events, identify patterns, and initiate routine workflows. Engineers still investigate unusual conditions, judge business impact, approve changes, and verify recovery. Automated conclusions also depend on the accuracy and coverage of the operational data.
How do platforms like ServiceNow split ITOM and ITSM?
Platforms such as ServiceNow present ITOM and ITSM as related capability areas. ITOM generally covers discovery, monitoring, and event information; ITSM covers the incident, request, change, and service delivery workflows. Organizations should examine how records and handoffs connect in the configuration they plan to deploy.
Which industries benefit most from running ITSM and ITOM together?
Financial services, healthcare, manufacturing, e-commerce, and managed service providers commonly operate services where interruption affects transactions, users, or production. Coordinating detection and service response helps these teams establish impact, prioritize restoration, and retain a shared incident history.