The incident management process gives IT teams a defined route from detecting a service disruption to restoring normal operations and confirming recovery. It establishes who owns the incident, how its business impact determines priority, when specialists take over, and what information must remain in the record. Without that structure, even a minor failure can become a prolonged exchange of emails and conflicting updates.
Within IT service management, incident handling follows eight operational steps and a broader five-phase lifecycle. They link business impact, technical recovery and user confirmation to a consistent record.
What Is Incident Management?
Incident management is the practice of responding to unplanned interruptions or reductions in service quality, restoring normal service as quickly as circumstances permit, and limiting the consequences for users and business operations. The focus is recovery: the investigation into why a fault appeared may continue after service has resumed.
ITIL describes its purpose in terms of minimizing incident impact through prompt restoration. The ITIL incident management practice gives organizations guidance on ownership, communication and coordinated recovery; each enterprise defines the detailed workflow, thresholds and escalation responsibilities for its own environment.
Monitoring alerts and employee reports may describe the same failure. A shared record connects these signals to the affected service.
What Is an Incident in ITSM?
An incident is an unplanned interruption to an IT service or a reduction in the quality of that service. It can involve a complete outage, degraded performance or a failure affecting only one employee. An underlying cause can remain unknown when the record is opened.
Three common incidents illustrate the range:
- Individual access failure: An employee receives repeated login errors despite using the approved identity process.
- Service degradation: A finance application remains accessible, but reports that usually open in seconds now take several minutes.
- Business-wide outage: A shared network component fails, interrupting order processing across several sites.
All three need ownership and an outcome the requester can verify. They differ in urgency, scope, expertise and communication requirements. An approved request for new access, by contrast, follows request fulfillment unless an existing service has unexpectedly stopped working.
Objectives of Incident Management
A defined incident practice aims to:
- Restore usable service quickly, using an approved workaround when a permanent repair requires more time.
- Reduce disruption to transactions, employee work, customer activity and contractual commitments.
- Give service desks, technical responders and stakeholders a shared picture of impact, ownership and progress.
- Apply consistent severity, priority and escalation decisions across sites and operating hours.
- Retain reliable records for service reviews, trend analysis and corrective action.
Incident vs Event vs Problem vs Service Request
| Record type | What it represents | Example | Typical owner or next action |
|---|---|---|---|
| Incident | An unexpected interruption or service degradation | Payroll portal unavailable | Service desk or incident manager coordinates restoration |
| Event | A change in the state of a monitored component or service | Disk usage reaches a defined threshold | Operations reviews IT event management rules and alert relevance |
| Problem | The cause, or potential cause, of one or more incidents | Repeated database connection exhaustion | Problem management investigates recurrence and lasting fixes |
| Service request | A predefined request from a user | Employee requests approved software | Request fulfillment follows the service catalog and approvals |
An event becomes an incident when service disruption or credible degradation requires coordinated restoration. A recurring incident may lead to a problem record, but urgent recovery can proceed before a full root-cause investigation finishes. Distinguishing these records avoids measuring routine requests as outages or treating every low-level alert as an employee-visible failure.
What Is the Incident Management Process?
The incident management process is the operating sequence that determines how a disruption enters the service desk, receives business priority, reaches an accountable resolver and moves to verified closure. It applies to reports submitted by employees as well as incidents generated by monitoring, provided the organization has defined which events warrant a service record.
The service desk handles registration and closure; resolver teams diagnose faults, while an incident manager coordinates complex cases.
Skipping logging, priority review or user verification may appear to accelerate a single ticket. Across a busy service desk, those omissions create duplicate cases, weak audit trails and repeated diagnosis. A reliable sequence preserves speed while making the work traceable.
Incident Management vs Incident Response
These disciplines can overlap during a security-related outage, yet their immediate aims differ. Incident management restores an affected IT service and coordinates its business-facing consequences. Cybersecurity incident response investigates malicious activity, contains threats, protects evidence and guides recovery after a breach or suspected compromise.
For example, a mailbox outage may begin as a service incident. If investigation reveals account takeover or malicious changes, security responders join under a separate evidence and containment procedure. Service restoration, user communication and security investigation then proceed with agreed ownership and decision authority. See the incident response phases for the security-focused sequence.
Explaining the Incident Management Lifecycle
The incident management lifecycle groups the operational work into five phases: detect → respond → restore → close → learn. Each phase describes a distinct outcome within the same incident record.
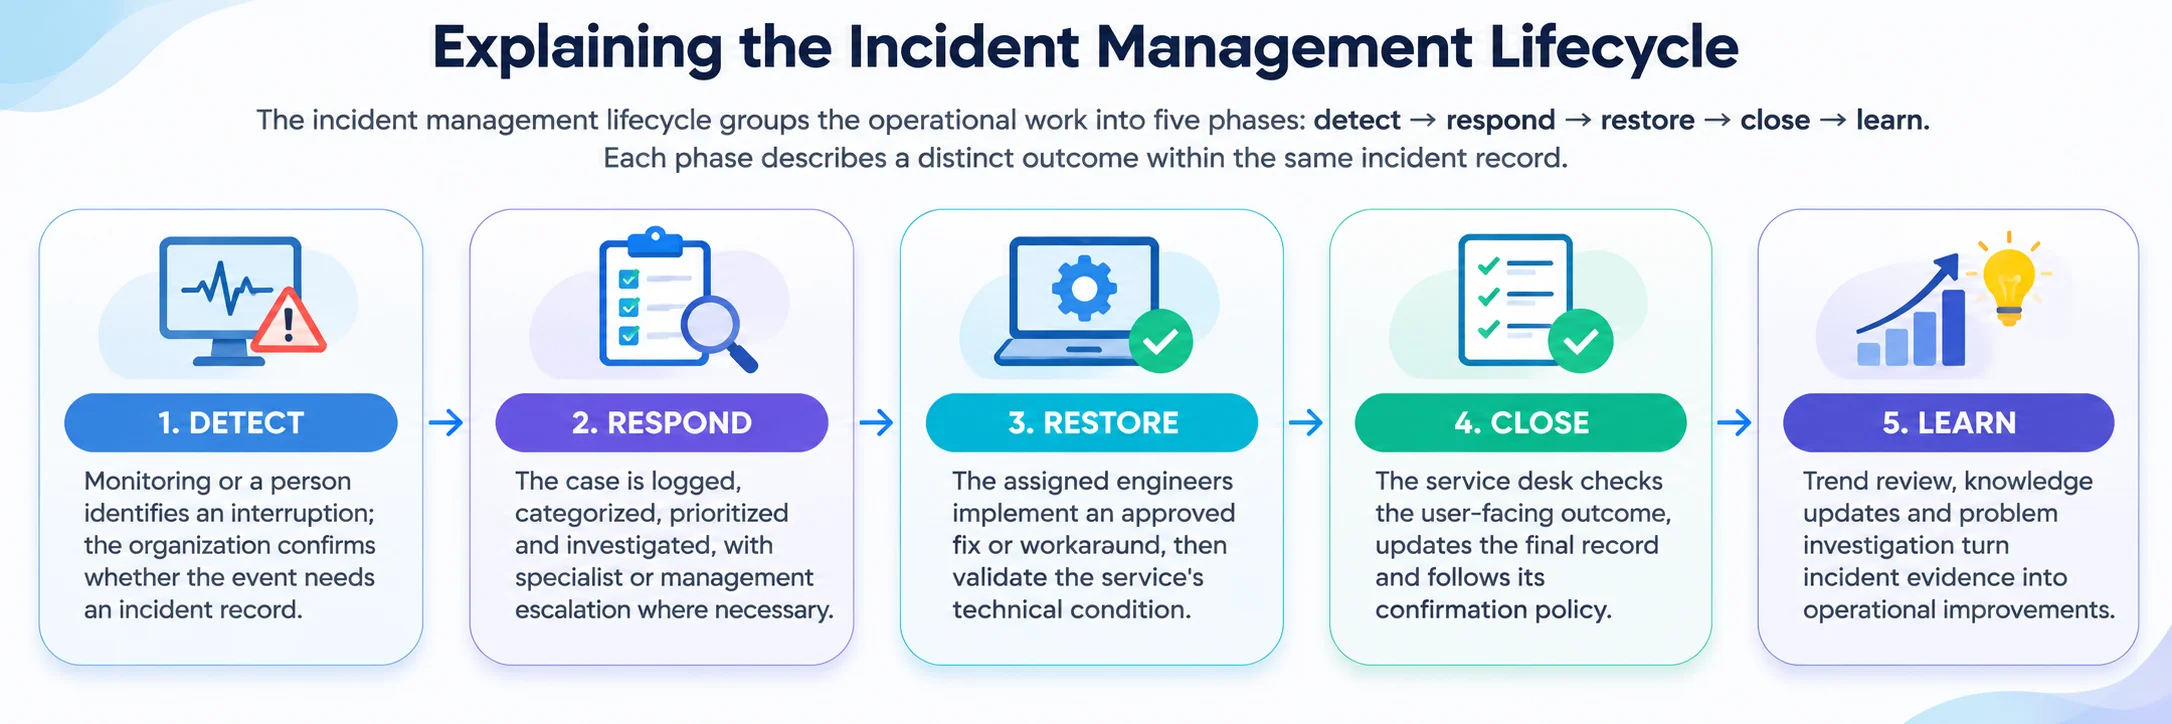
- Detect: Monitoring or a person identifies an interruption; the organization confirms whether the event needs an incident record.
- Respond: The case is logged, categorized, prioritized and investigated, with specialist or management escalation where necessary.
- Restore: The assigned engineers implement an approved fix or workaround, then validate the service’s technical condition.
- Close: The service desk checks the user-facing outcome, updates the final record and follows its confirmation policy.
- Learn: Trend review, knowledge updates and problem investigation turn incident evidence into operational improvements.
The eight process steps are a more detailed view of the first four phases. Identification maps to detection; logging through escalation falls largely within response; resolution covers restoration; closure stands as its own step. Learning continues after closure through reviews and improvements, especially for recurring or high-impact disruptions.
Cases can return to diagnosis when restoration fails verification. Record each reassignment rather than moving a ticket forward merely to satisfy a workflow state.
Incident Management Process Steps (8-Step Process Flow)
The eight steps create a repeatable path from initial signal to completed record. Organizations can automate portions of the route, but ownership, business priority and evidence of restoration still require clearly assigned responsibility.
Step 1: Identification
Identification begins when an employee reports a failure, a monitoring platform detects an abnormal condition or an operations engineer discovers degraded performance. The first task is to determine what has changed, which service may be affected and whether an existing incident already covers the issue.
For instance, a database latency alert and fifteen complaints about delayed checkout may represent one disruption. Creating sixteen independent investigations would fragment the timeline. Link related reports to a primary incident where the service desk policy permits, preserving affected users and observations without multiplying work.
Common channels include:
- Monitoring alerts from infrastructure, networks, applications and cloud services.
- Employee submissions through self-service portals, telephone, email or collaboration channels.
- Chatbots that capture symptoms and escalate unresolved cases to an agent.
- Supplier advisories or proactive health checks performed by operations personnel.
Each channel needs a consistent rule for creating or updating a ticket. Alert relevance and service impact determine whether an incident record is needed.
Step 2: Logging
Logging creates the shared record used throughout recovery. It should capture enough detail for routing and initial investigation without delaying urgent assistance for an employee who knows little about the technical cause.
Use one primary incident identifier to connect updates, actions, communications and related cases. Preserve the original detection time separately from the time a ticket was entered; otherwise, delays between alert and registration disappear from reporting. For high-priority cases, details can be enriched as engineers begin restoration.
Minimum Fields for an Incident Record
| Field | What to capture | Why it matters |
|---|---|---|
| Incident ID and timestamps | Unique ID, first observed time, logged time | Traceability and accurate timelines |
| Affected service | Application, site, business service or configuration item | Impact assessment and ownership |
| Reported symptoms | Error text, failed task, performance change | Faster triage without repeated questions |
| Source and contact | Alert reference, requester, callback details | Follow-up and linked evidence |
| Business impact | Affected users, transactions, locations | Priority and communication scope |
| Priority and status | Agreed priority, current state, SLA clock | Queue and deadline management |
| Assigned owner | Accountable group, named responder, escalation contact | Clear responsibility during handoffs |
| Actions and evidence | Tests, changes, workaround, restoration checks | Continuity, closure and later review |
Restrict sensitive attachments and credentials according to the organization’s access policy. A ticket needs diagnostic context, rather than unrestricted copies of personal records or secrets.
Step 3: Categorization
Categorization identifies the type of failure and the service involved. Useful categories usually combine a business-facing service with a technical or functional classification: email access, application performance, endpoint connectivity or network interruption. Overly broad labels such as “other” conceal patterns; excessively granular menus increase misclassification.
Choose categories agents can apply consistently with the information available at intake. Specialist responders can refine technical attributes during investigation while keeping the original classification history. Clean category data helps managers identify recurring issues, repeated ownership transfers and areas where knowledge articles would reduce routine diagnostic effort.
For example, separating VPN authentication failures from unreachable gateways reduces misrouting. Revisit categories that agents frequently correct.
Step 4: Prioritization
Priority combines impact—how widely or seriously the incident affects business activity—with urgency—how quickly action is required. An interruption affecting one payroll approver just before a statutory cutoff can be more urgent than a temporary slowdown affecting a larger group during a quiet period.
Use defined business services, contractual commitments and recovery windows rather than relying exclusively on the number of tickets received. An impact–urgency matrix maps these assessments to P1–P5. Assign a provisional value when facts remain uncertain; review it as impact evidence changes, recording who revised the decision and why.
Priority sets response targets and escalation; severity describes disruption, while major-incident status activates a separate coordination procedure.
Step 5: Initial Diagnosis
Initial diagnosis starts with the symptoms and the service outcome the user needs restored. Agents check relevant knowledge articles, prior incidents, monitoring views, known errors and recently approved changes. Basic tests can establish whether the issue affects one account, an office, a location or a shared application dependency.
Record tests and their results. “Restarted application worker at 10:14; two logins recovered; checkout remains slow” gives the next engineer far more information than “service restarted.”
Where a documented workaround restores a business task safely, use it while longer investigation continues. Distinguish an accepted workaround from a verified permanent correction. For security-sensitive systems, diagnosis and remediation must respect access approvals, change rules and the authority of the incident manager.
Step 6: Escalation
Escalation transfers expertise or decision authority when the present owner cannot complete restoration within the required time or scope. It works best as an anticipated route rather than an admission that someone has failed.
A usable escalation policy defines triggers, receiving teams, contact channels, on-call coverage and the minimum information handed over. The original incident remains traceable even when several resolver groups participate. Every transfer should identify the next accountable responder and preserve work already completed.
Functional Escalation
Functional escalation moves technical work from an initial service agent to a specialist group, such as network engineering, databases or a vendor. It may occur immediately for a known high-complexity fault or after a limited first-line diagnostic window. Include the observed symptoms, prior tests, incident priority and links to relevant telemetry.
Hierarchical Escalation
Hierarchical escalation involves service or business leadership when impact, risk, resource conflict or communication demands exceed normal team authority. A cross-region outage may require an executive update and approval for emergency resources while engineers continue restoration. Management involvement adds coordination rather than replacing technical responsibility.
Monitoring for SLA Breach
A separate escalation trigger can be tied to response or restoration targets. Warning thresholds alert owners before a deadline expires; breach procedures identify who receives the case and which recovery options remain. Review paused clocks, business-hour calendars and ownership changes. An automatic reminder sent to an empty queue gives the appearance of control without accelerating the response.
Step 7: Resolution and Recovery
Resolution applies a remedy or workaround that returns the affected service to a usable state. Recovery includes technical checks, business transaction verification and observation for early relapse. A router may show green status while a dependent application still fails; both conditions must be examined before declaring success.
Record the restoration action, responsible engineer, verification method, remaining limitations and any follow-on work. Emergency changes need their required authorization and traceable links. Where the fault remains unresolved beneath a temporary workaround, create the appropriate follow-up investigation while keeping the incident outcome accurate.
Verify the failed business transaction wherever practical, rather than relying only on system health checks.
Step 8: Closure
Closure confirms that the agreed service outcome has been restored and the incident record contains enough information for audit, reporting and future reference. It differs from the technical act of marking a device healthy. A resolved case may remain open pending user verification or an agreed closure interval.
Who Can Close an Incident?
The service desk ordinarily controls formal closure under its organization’s policy. The requester or a designated service owner confirms successful restoration where possible. For unattended alerts, pre-agreed technical verification may substitute for an individual reply. The team should define how many contact attempts are made, when automatic closure can occur and how a user reopens a case if the problem returns.
Feeding Closure into Knowledge and Problem Management
Write a concise final account of symptoms, cause if established, actions and outcome. A repeatable workaround can become a knowledge article after technical review. Linked incidents showing the same unexplained failure should trigger investigation into recurring causes. This keeps incident restoration distinct from longer-term remediation while retaining a useful trail between them.
Understanding the Incident Management Workflow
A workflow translates the process steps into decisions, owners and transitions that service personnel can follow under pressure. It needs entry criteria for new reports, branches for service requests and major incidents, a route for unresolved first-line cases and a closure gate that verifies recovery.
Standard Incident Workflow
A typical case begins with an alert or employee report, followed by classification and business priority. The service desk checks for an existing incident, creates or updates the record and attempts the authorized initial diagnosis. If first-line action resolves the issue, the agent verifies service and proceeds toward closure. Otherwise, a functional resolver accepts the case and continues investigation.
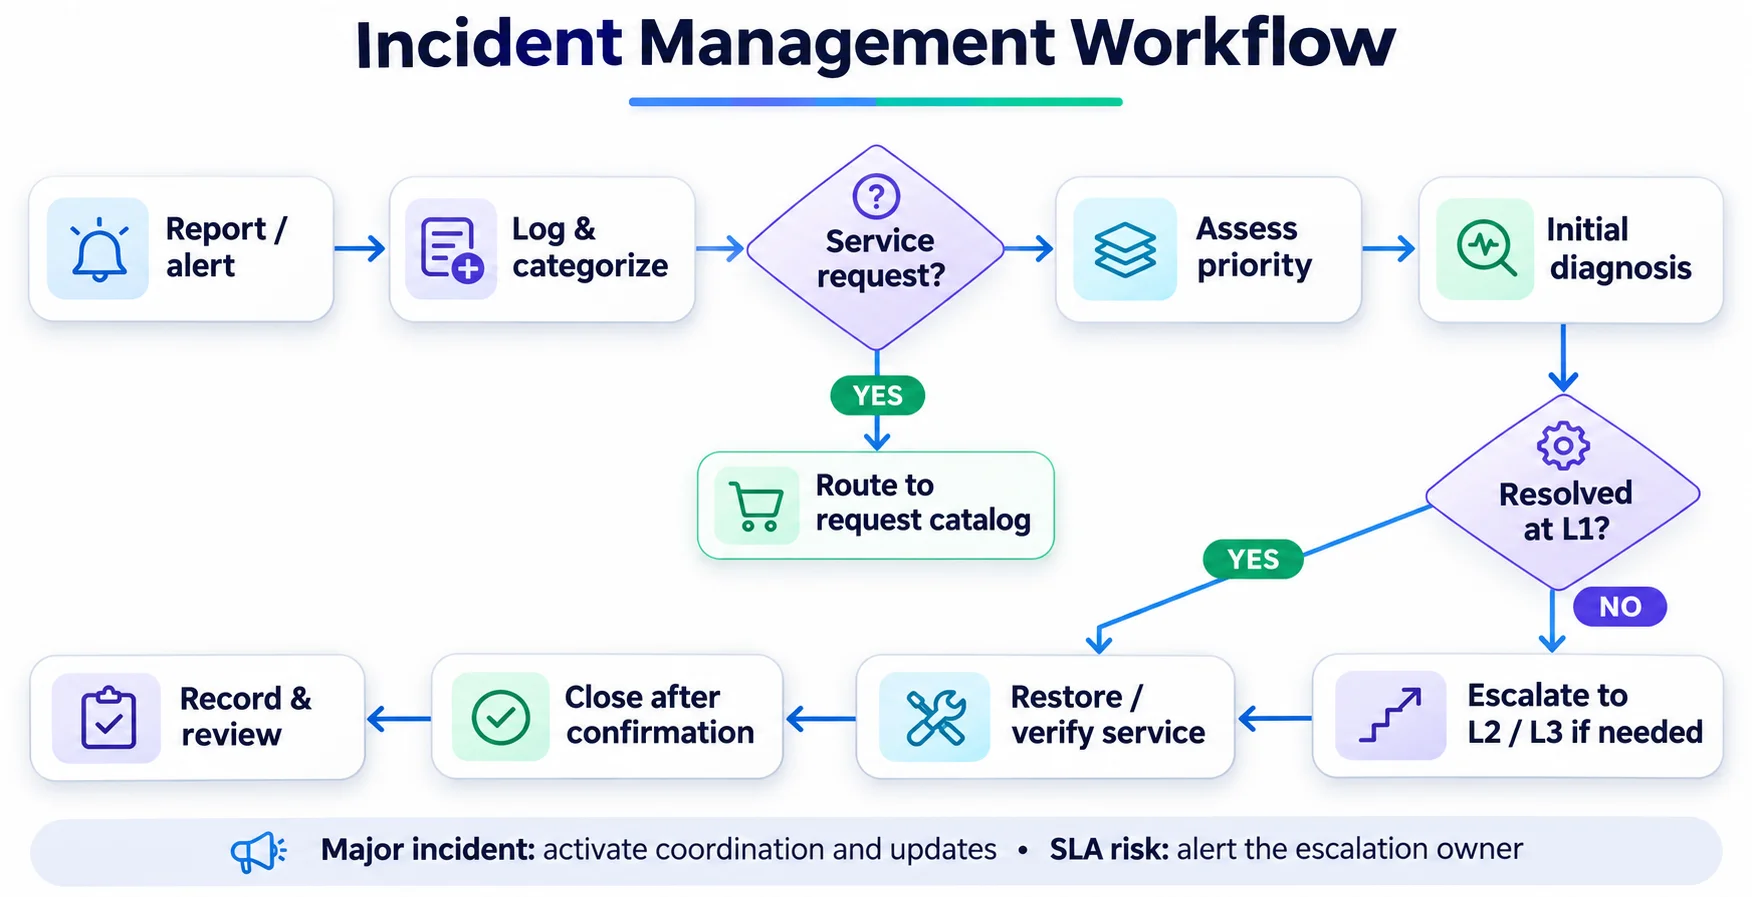
Three decisions deserve clear workflow rules:
- Is the record actually a service request? Route an approved access or provisioning request through fulfillment rather than incident response.
- Does impact meet the major-incident declaration threshold? Open the command and communication track while technical investigation continues.
- Is an SLA breach approaching? Invoke an escalation owner and revised recovery plan before the target is missed.
A ticket status should represent an actual state: awaiting requester evidence, active investigation, restored pending confirmation or closed. Status changes made solely to pause a clock obscure elapsed time and undermine service reporting.
Major Incident Workflow
Major incidents add a parallel coordination track. A designated manager declares the event, opens a response bridge, assigns a technical lead and sets a stakeholder update interval. Technical teams continue diagnosis while communications personnel publish impact and restoration updates. Changes to scope, priority or anticipated recovery are logged in the primary incident.
After service restoration, the response bridge can close. A post-incident review and corrective-action register remain open until assigned owners finish the agreed work. This frees technical responders to focus on recovery.
Incident Priority Matrix and Severity Levels
The priority model translates business impact and urgency into a consistent queue order. Organizations often define impact as high, medium or low, then combine it with urgency to select a P1–P5 priority. The policy must state what each category means for the actual services involved; the same number of affected users can carry different consequences across different applications.
Impact × Urgency Priority Matrix
| Impact / Urgency | High urgency | Medium urgency | Low urgency |
|---|---|---|---|
| High impact | P1 – Critical | P2 – High | P3 – Medium |
| Medium impact | P2 – High | P3 – Medium | P4 – Low |
| Low impact | P3 – Medium | P4 – Low | P5 – Planned |
High impact could mean a revenue transaction halted across sites or a critical internal function unavailable. High urgency may mean an approaching operational deadline or a condition that is rapidly worsening. P5 can cover a low-consequence incident with a documented workaround, while P1 prompts immediate mobilization and continuous coordination until the service is stabilized.
A manager should be able to explain each assignment in one sentence. “P2 because one finance site cannot submit time-sensitive settlement files” is more useful than “P2 because several users complained.” Review the rating if the affected population, business timing or workaround changes. Changes in priority belong in the incident history.
Severity Levels (S1–S4)
Severity records the seriousness of a service disruption using an S1–S4 scale. Some enterprises align their severity and ticket priority labels; others maintain separate attributes for technical condition and business handling. The definitions must be explicit before teams compare performance across divisions.
- S1 – Critical: Complete loss of a business-critical service, or failure with broad, immediate operational consequences.
- S2 – High: Major functionality unavailable or degraded, with substantial business disruption and limited recovery options.
- S3 – Medium: A subset of users or functions affected, with a workable alternative or contained operational impact.
- S4 – Low: Minor degradation or intermittent behavior with limited business consequence and a reliable workaround.
A high-severity technical incident can require rapid engineering work even before its full business impact is known. Conversely, a localized failure can earn high business priority near a contractual deadline. Service owners should reconcile those signals rather than automatically equate severity, priority and major-incident status.
SLA Response and Resolution Targets
A service level agreement defines the commitments against which an incident is assessed. Response time typically measures how quickly the responsible team acknowledges or begins handling a case; resolution time measures the interval to the agreed restoration outcome. The starting clock, pause rules and operating calendar need written definitions.
| Severity | Illustrative response target | Illustrative restoration target | Operational expectation |
|---|---|---|---|
| S1 – Critical | 15 minutes | 4 hours | Immediate coordination and frequent business updates |
| S2 – High | 30 minutes | 8 hours | Assigned specialist and managed escalation |
| S3 – Medium | 2 hours | 24 hours | Tracked queue, status updates and scheduled follow-up |
| S4 – Low | 8 hours | 72 hours | Standard ownership and planned recovery |
Some organizations use separate targets for initial response, workaround availability and full restoration. This distinction matters where a temporary recovery restores transactions while a permanent repair requires a later maintenance window. Report which target was met rather than treating all deadlines as interchangeable.
Major Incident Management Types
Major incident management introduces focused command, accelerated communication and cross-team coordination for disruptions that meet pre-agreed business thresholds. It exists because ordinary ticket routing may be too slow when a critical service is unavailable across an organization or a time-sensitive operation is jeopardized.
How to Define a Major Incident
A major incident declaration should depend on documented criteria, such as loss of a critical service, widespread customer impact, severe regulatory exposure or an outage threatening a time-bound business activity. A P1 ticket often qualifies, yet the two labels serve different purposes: priority determines queue urgency; major status activates a coordinated management procedure.
Assign authority to declare and stand down a major incident. Define who may override initial severity and how business owners contribute impact evidence. A short checklist can prevent delayed decisions:
- Which named business service has failed, and what work can users still complete?
- Are critical locations, customers or contractual operations affected?
- Is restoration ownership clear, and are specialist groups mobilized?
- Does the situation demand a central communication channel and executive visibility?
- What new evidence would justify changing the declaration or response level?
Communicating During a Major Incident
A major incident manager sets the reporting rhythm early, even when engineers have yet to identify a cause. The first update should establish known impact, the affected service, current response ownership and the time of the next communication. Later messages distinguish verified facts from hypotheses and record any workaround available to users.
Communication responsibilities are separate from fault isolation. A service owner may brief business leaders, while the technical lead coordinates diagnostics and the service desk handles employee questions. A status page or agreed broadcast channel reduces repeated requests for updates. Set a cadence that reflects business urgency, and revise it explicitly when the situation changes.
Post-Incident Review
Once operations stabilize, a blameless review examines decisions and conditions that shaped the response. It should answer five questions: What happened? How was the issue detected? Which actions sped up or slowed restoration? How did communications match actual impact? What changes would reduce recurrence or shorten the next recovery?
Capture the timeline from incident records and monitoring evidence rather than reconstructing it entirely from memory. Give corrective actions named owners, deadlines and acceptance tests.
Roles and Responsibilities in Incident Management
An incident can involve several specialist groups, but it still needs clear accountability for classification, restoration coordination, business communication and closure. Define these duties in operating procedures and train participants using scenarios from their own services.
Service Desk (L1)
The first-line team receives reports, registers incidents, performs permitted checks, identifies duplicates and communicates with requesters. L1 agents monitor queue age and time targets, route incidents according to category and priority, and verify closure evidence. Their training should cover business impact questions as well as ticket fields.
Resolver Groups (L2/L3)
Specialist teams investigate application, identity, database, infrastructure or vendor faults. They document diagnostic results, carry out authorized recovery, confirm technical health and explain remaining risk to the incident owner. L2/L3 engineers should receive enough context to begin useful work without repeating the initial interview or tests.
Incident Manager
The incident manager monitors progress, resolves ownership disputes, coordinates cross-team tasks and escalates emerging recovery risks. During ordinary incidents, this role may be assigned to a service desk lead. Its authority should include calling review meetings, requesting updates and raising decisions that need business-owner involvement.
Major Incident Manager
For declared major incidents, the major incident manager directs the coordination bridge, assigns communications duties, tracks decisions and confirms the criteria for closing the emergency response. A technical lead remains accountable for diagnosis and recovery. Separating these duties prevents an expert engineer from being pulled away from restoration to manage every stakeholder question.
Benefits of a Structured Incident Management Process
A disciplined response method brings order to interruptions that would otherwise depend on individual memory, informal chats and repeated escalation calls. Its value appears through faster recovery, clearer ownership and service data that leaders can act on.
Lower Downtime and MTTR
Consistent intake, early classification and reliable escalation cut the time lost before the right specialist begins diagnosis. Links to recent changes, relevant equipment and previous fixes can shorten investigation. Mean time to restore (MTTR) improves when each stage removes waiting or repeated effort; automation alone cannot compensate for unresolved ownership.
A useful review divides the total restoration interval into detection, registration, assignment, investigation and recovery. This shows whether the largest delays occur before technical work begins or during the repair itself. The distinction guides investment in staffing, monitoring, knowledge or engineering reliability.
Transparency and Visibility for Users
An incident record with a named owner and reliable updates reduces uncertainty for affected employees. The requester can follow progress and understand when the next communication is expected. During wider outages, status messages also reduce duplicate submissions that distract the desk from identifying newly affected services.
Transparency requires accuracy. An optimistic recovery estimate that changes repeatedly can erode trust, whereas a clear description of current impact and the next update time gives people information they can use to plan work.
Consistent SLA Compliance
Shared priority rules, clock definitions and timely escalation create a dependable basis for meeting service commitments. Supervisors can identify cases nearing a deadline and intervene while recovery options remain. The reporting value extends beyond pass rates: a breach can be traced to delayed intake, an incorrect queue, missing specialist cover or prolonged diagnosis.
Fewer Repeat Incidents
Closure data reveals patterns that individual responders may miss. Repeated access failures after password policy changes, for example, could lead to an identity configuration review; recurring switch alarms may justify replacement or capacity work. The objective is to move from isolated temporary recoveries toward fewer interruptions, based on evidence and assigned corrective actions.
Better Employee and Customer Experience
Employees care about regaining the ability to complete work, knowing who is dealing with the disruption and receiving useful updates. Customers judge the outcome through transaction success and service availability. A well-run process connects technical recovery with these experiences, so an incident is never declared finished simply because a server responds to a health check.
Why Run Incident Management Inside an ITSM Platform
Running the process within an ITSM tool can connect the incident record with service ownership, knowledge, assets, approvals and agreed response targets. Agents gain a shared history across shifts; managers can inspect queue, breach and restoration trends without manually reconciling spreadsheets.
The workflow still needs clear roles and practical procedures. A central application records decisions, while people determine business priority, investigate unusual faults and verify service recovery. Organizations comparing capabilities can examine incident management tools separately from the operational method itself.
Best Practices of Incident Management
Strong incident practices depend on a small number of operating habits executed consistently. They should fit the risks and working hours of each service, with room to adjust as ticket data reveals recurring weaknesses.
Define a Major Incident Before You Need One
Document declaration thresholds, responsible roles, responder contacts and communication authority. Exercise the process against a realistic application outage before a crisis exposes missing decisions. Include an evening or weekend scenario so escalation paths are tested beyond normal staffing hours.
Keep the Knowledge Base Current
Knowledge articles should answer the questions that delay initial diagnosis: how to recognize a failure, which checks are safe for L1, when specialist involvement is required and how successful recovery is verified. Assign owners and review dates. Retire obsolete workarounds that refer to systems or settings that have changed.
Automate Assignment and Notifications
Automate repetitive routing where categories and ownership rules are dependable. Service-desk automation can acknowledge a new report, create an incident from selected monitoring events or warn an owner about approaching deadlines. Build exception paths for uncertain classifications and absent responders. Review false assignments and duplicate alerts before expanding automation to more services.
Connect Monitoring, CMDB and Change Management
Monitoring identifies changing technical conditions. A CMDB maps the components and service relationships that give those alerts business context. A recent change management record can explain which configuration was altered before the fault appeared.
Choose a few business-critical services and validate those connections first. Inconsistent asset identifiers or stale dependency maps can misdirect responders; assign data ownership and investigate mismatches rather than importing every source indiscriminately.
Run Blameless Reviews
Incident reviews should examine contributing conditions, assumptions and decision points without turning the meeting into personal criticism. Staff are more likely to record near misses and incomplete information when the discussion focuses on better controls. Translate lessons into revised playbooks, tests, monitoring thresholds or access procedures with accountable owners.
Review the Process Every Quarter
Track the slowest handoffs, recurring categories, reopened incidents and missed targets. Select a manageable set of changes, assign a person to each and verify results using later incidents. Treat continual service improvement as a recurring management activity rather than a once-a-year rewrite of procedures.
Incident Management KPIs to Track
Five incident measures make a practical starting scorecard; related ITSM metrics cover wider service performance.
| KPI | Calculation or observation | Interpretation risk |
|---|---|---|
| Mean time to restore (MTTR) | Total restoration time ÷ number of restored incidents | Mixing ticket closure with verified service recovery |
| Mean time between failures (MTBF) | Operating time ÷ number of failures for a repairable service or asset | Comparing unrelated systems or changing observation periods |
| First response time | Time from logged incident to first qualifying response | Counting automatic acknowledgments as active investigation |
| SLA compliance rate | Cases meeting the defined target ÷ eligible cases × 100 | Ignoring priority mix, pauses and operating calendars |
| Reopen rate | Reopened incidents ÷ closed incidents × 100 | Treating premature closure as faster restoration |
Review these figures by priority, business service and resolver group. A falling average restoration time can conceal a small number of high-impact incidents that grew worse. Pair numeric trends with a sample of actual case histories, especially reopened tickets and events that triggered major-incident coordination.
Examples of the Incident Management Process
Consider a hypothetical P2 disruption at a company with several offices. The email service remains operational company-wide, but users in one branch cannot reliably send messages to external recipients. The business impact is contained, yet the branch is exchanging time-sensitive supplier documents. The eight steps unfold over the next 72 minutes.
| Time | Step | Incident action |
|---|---|---|
| 09:05 | 1. Identification | Monitoring flags mail delivery failures; two employees report bounced messages |
| 09:08 | 2. Logging | L1 creates incident INC-2048 and links both employee reports |
| 09:11 | 3. Categorization | Record marked “Email – outbound delivery,” affected site and service owner captured |
| 09:14 | 4. Prioritization | P2 assigned because supplier communication is time-sensitive, with limited impact outside the branch |
| 09:19 | 5. Initial diagnosis | Agent verifies internal mail works and external messages fail; gateway knowledge checks begin |
| 09:27 | 6. Escalation | Messaging specialist accepts the case with test results and gateway alerts attached |
| 10:02 | 7. Resolution and recovery | Corrected mail-routing configuration restores external delivery; three test messages succeed |
| 10:17 | 8. Closure | Branch coordinator confirms documents were delivered; L1 records action and closes case |
The elapsed interval from the first alert to verified restoration was 57 minutes; formal closure followed 15 minutes later. Those timestamps describe different outcomes and should be recorded separately. If investigation reveals the same configuration drift behind previous incidents, the messaging team can raise follow-on corrective work while leaving this case accurately closed.
A useful after-action check asks whether the priority reflected the branch’s deadline, whether the escalation carried enough diagnostic context and whether monitoring could identify the configuration fault earlier. These questions convert a routine recovery into information for improving the next response.
Incident Management by Industry
The same process stages apply across industries, although business-impact definitions, escalation authority and restoration evidence vary with the services involved.
Banking, Financial Services and Insurance
A disrupted payment gateway can affect settlements, merchant transactions or account access. Priority needs to reflect processing windows and transaction exposure; closure may require successful sample payments, reconciliation checks and documented communication to accountable business teams.
Telecommunications
A fault in a shared network element may generate numerous alarms and customer reports across several regions. Correlation and service mapping help the operations group identify the common component while service management coordinates customer-specific impact, field dispatch and restoration confirmation.
Government and Public Services
Citizen portals and internal agency services can carry strict availability, access and record-retention requirements. Incident coordinators need dependable audit histories and communication plans that distinguish public disruption from internal service failure, especially where several departments use a common infrastructure service.
Oil and Gas
Remote sites, communications links and operational technology can create complex dependencies. IT incidents affecting field reporting or monitoring need clear separation between business-service restoration and safety-critical plant procedures. Site authorities and technical responders should follow the organization’s established operational and safety escalation rules.
Emerging Trends in Incident Management
Three developments are changing how incident teams collect context and coordinate work:
- AIOps-assisted triage: Event grouping and likely-cause suggestions can reduce duplicate investigations. AI-powered incident management brings its own data-quality and approval considerations; engineers still validate major recovery decisions.
- ChatOps coordination: Integrations with workplace collaboration channels help incident owners publish status, record decisions and bring specialists into a shared response. The incident record should remain the authoritative history.
- SRE methods: Service level objectives, error budgets and recovery exercises create stronger links between incidents, engineering reliability work and business risk.
These approaches add value where they shorten meaningful delays. More alerts, dashboards or automated messages can make coordination harder unless ownership, service context and escalation rules are already clear.
How Infraon Fits the Incident Management Process
Infraon ITSM brings incident registration, classification, assignment, service-level monitoring and reporting into one service workflow. Its incident handling can draw on self-service intake, knowledge records, automated routing and escalation rules, with related operations information available through the wider Infraon portfolio.
For a distributed enterprise, a practical implementation begins with a few critical services. Configure categories, responder ownership, business impact rules and the thresholds that govern escalation. Connect selected monitoring alerts and verify that duplicates are grouped, the correct resolver receives the record and stakeholders can follow progress. Review incident history and restoration results before expanding across sites.
The objective is a traceable path from report or alert to verified recovery, with fewer manual handoffs and a consistent account of what occurred. Begin with an agreed operating policy, then configure the workflow around it.
Frequently Asked Questions
What are the steps of incident management?
The eight steps are identification, logging, categorization, prioritization, initial diagnosis, escalation, resolution and recovery, and closure. They organize how a disruption becomes a managed service record, reaches an accountable technical responder and returns to normal operation. Later trend analysis and review use the completed record to guide improvements.
What is the incident management lifecycle?
The lifecycle groups incident work into five phases: detect, respond, restore, close and learn. The eight steps describe the day-to-day actions inside those phases. Learning can continue after the incident is formally closed, while difficult cases may move backward through diagnosis and escalation before recovery is verified.
What is an incident in ITSM?
An incident is an unexpected interruption to an IT service or a reduction in its quality. Examples include failed email delivery, degraded application performance and network outages. The service desk records impact and coordinates recovery; a routine request for new equipment or approved access follows a separate fulfillment path.
What is the difference between an incident and a problem?
An incident records a service disruption requiring restoration. A problem concerns the underlying cause, or potential cause, of one or more incidents. Engineers may recover service through a workaround before identifying that cause. Related cases can feed a later investigation into recurrence and longer-term preventive changes.
What is a major incident?
A major incident meets predefined criteria for elevated business impact and requires coordinated management beyond normal ticket routing. The organization assigns a manager, technical lead and communication cadence. A major incident often has high priority, although declaring it activates additional responsibilities rather than simply changing the ticket number or severity label.
How is incident priority calculated?
Priority generally combines impact and urgency. Impact describes the scope and seriousness of the interruption; urgency describes how quickly action is needed. A three-by-three matrix can translate those assessments into P1–P5 queue priorities, with documented exceptions for critical deadlines, service commitments and changing business conditions.