ITSM modernization in Malaysia often starts when an enterprise realizes its service desk can no longer keep up with the work it receives. An incident moves through shared inboxes, approvals are buried in email, and monthly SLA reports require hours of manual reconciliation. For CIOs overseeing offices in Kuala Lumpur, Penang, Johor, or several business units, the challenge is deciding what to change without disrupting daily service. A phased migration roadmap provides a way to assess the current system, test a manageable workflow, and expand from proven results.
Why ITSM Modernization Is a Priority for Malaysian Enterprises
Enterprise service desks can remain operational for years while accumulating hidden costs. Teams add spreadsheets when the ticketing system lacks a field, email approvals when workflows become difficult to modify, and separate dashboards when incident data and monitoring records cannot be joined. The result may still look acceptable in a monthly SLA report even as employee effort and unresolved handoffs continue to rise.
Signs Your Current Service Desk Has Reached Its Limits
Before committing to a legacy ITSM migration in Malaysia, CIOs can ask operational questions that reveal the actual constraints:
- Are ticket volumes increasing while resolution capacity stays flat?
- Do employees contact several teams to learn who owns a request?
- Can an auditor reconstruct a service change from its original request to approval and execution?
- Do service agents re-enter device or incident information from monitoring and asset systems?
- Are SLA reports assembled manually from exports that use different definitions?
- Does a recent outage reveal missing ownership, repeated escalations, or delayed communication?
The answers help distinguish isolated configuration problems from limitations that require a wider system decision. A single missed approval may need a workflow correction; repeated failures in several departments suggest an underlying operating issue.
A useful test is to follow a single incident from the employee’s first message to final confirmation. Count the number of times information is copied between systems, approvals are chased manually, or responsibility changes without a record. Repeat the exercise for a service request and a planned change. If each workflow produces different gaps, the weakness may indicate a wider operating issue than a misconfigured ticket form.
CIOs should also check what happens outside normal business hours. A branch outage discovered on Saturday can expose dependencies on a weekday-only approval contact or a local engineer whose escalation details are missing. These exceptions reveal how resilient the operating model is under pressure.
What Legacy ITSM Looks Like in Practice
Legacy service management often combines an aging ticket tool with local workarounds. A facilities employee requests access through email, an IT agent copies the details into a spreadsheet, and a manager approves the request in another thread. At closure, the record says “completed” but contains little evidence about who approved access or when the underlying change occurred.
The same pattern appears in distributed organizations. A service desk serving Klang Valley headquarters and manufacturing sites in Penang may keep separate queues and spreadsheet inventories. Different teams calculate resolution time differently, leaving leadership with reports that resist comparison. Modernization begins by documenting these gaps rather than replacing every familiar system at once.
Four Operational Gaps Holding Back Enterprise IT Teams
Service Request Volume Outpacing IT Headcount
Password resets, access requests, and device provisioning can absorb an expanding share of agent time. When the same request passes through manual classification and repeated approvals, incoming volume rises faster than the team can close cases. Backlogs increase, employees send duplicate follow-ups, and managers lose visibility into actual demand. Left unresolved, routine workload crowds out major incident response and service improvement work.
Limited Visibility Across Infrastructure
A ticket may identify a failed business application while the related warning is visible only in a network console. Engineers then compare timestamps, contact infrastructure owners, and search logs before identifying the affected component. For organizations with branch networks or hybrid environments, every separate monitoring view extends the investigation. The cost is longer disruption, repeated diagnostic work, and slower communication to affected departments.
Governance and Audit Trails
ITSM records may contain decisions that auditors expect organizations to reconstruct later. Informal change approvals and unclear ownership create gaps even when the work itself was completed correctly. Governance problems grow as an enterprise adds subsidiaries, outsourced teams, or separate approval authorities.
ISO and Internal Audit Controls
Auditors may request evidence of who approved a change, the assessed risk, execution details, and any follow-up after failure. If parts of that history remain in email or individual workbooks, the audit requires manual collection and reconciliation. Missing records can delay reviews and make internal accountability harder to establish.
Data Handling and Access Logging Under PDPA
Service tickets frequently hold employee names, phone numbers, screenshots, or other personal data. Malaysia’s Personal Data Protection Act 2010, as amended by the Personal Data Protection (Amendment) Act 2024, makes data governance a consideration when migrating these records. The project team should identify who may view ticket information, which records are retained, and how access activity is recorded. The exposure from leaving these questions unresolved includes excessive access to personal records and gaps in incident investigation evidence. Legal obligations should be assessed for the organization’s actual activities and sector.
Data migration introduces an additional control question: which historical records require active access in the destination system? Ticket attachments can contain identity documents, employee information, or screenshots with personal details. Transferring every attachment into the same broadly accessible workspace can expand exposure. Teams should classify records, apply role permissions, retain an audit trail for data transfers, and obtain legal review of retention or cross-border handling requirements relevant to their operations.
Monitoring, Asset, and Service Desk Silos
Asset records may identify a laptop’s owner, monitoring may record its connectivity, and the service desk may hold the incident history. If the records use different identifiers, agents must verify basic facts by hand. Ownership changes can remain invisible until the next incident or asset audit. The continuing cost is duplicated administration, inaccurate service context, and repairs initiated with incomplete information.
Malaysia’s ITSM Modernization Roadmap
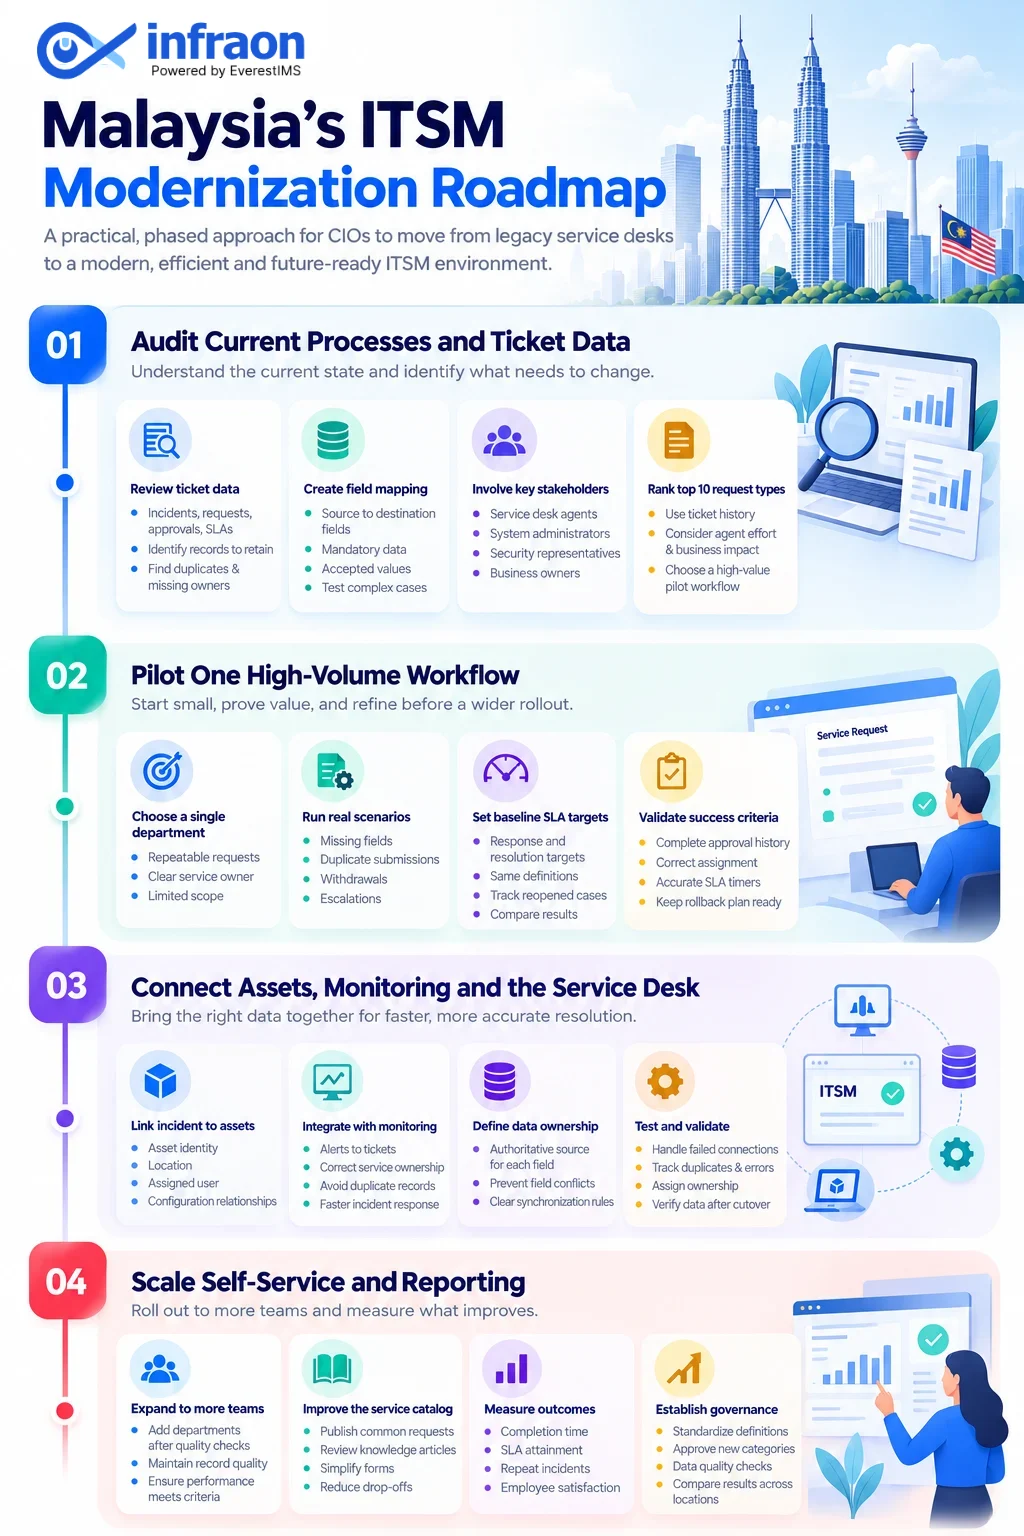
A successful migration should follow a sequence that produces evidence at every stage. CIOs can modernize IT service management in Malaysia through four phases, beginning with the requests users already submit and expanding after quality checks are passed.
Phase 1: Audit Current Processes and Ticket Data
Export a representative sample of incidents, requests, users, approvals, SLA fields, categories, and attachments. Identify which records need to remain searchable, which closed records meet retention rules, and which fields must be mapped before migration. Compare the source data with current reports to detect missing owners, duplicate categories, and inconsistent timestamps.
Invite service desk agents, system administrators, security representatives, and business owners to review the same sample. Their input exposes informal workflows that rarely appear in official procedure documents. Record baseline measures such as ticket volume by category, median resolution time, reopened incidents, and SLA attainment before any pilot changes begin.
Create a field-mapping register for the records that will move. It should identify each source field, destination field, accepted values, mandatory data, and the person responsible for validating the mapping. Test difficult cases first: tickets with several assignments, requests involving delegated approval, or incidents linked to retired assets. These records reveal migration defects that a sample of ordinary closed tickets may miss.
Separate operational records from archival material. Some organizations need closed tickets searchable for audits, while others can retain an export under controlled access. The decision should reflect legal and business retention requirements and be recorded before data is copied. A migration cutover is much easier to reconcile when the scope is clear.
Rank the Top 10 Request Types by Volume
Use several months of ticket history to identify the ten request categories creating the highest workload. Separate true service requests from incidents and remove duplicates caused by different naming conventions. Select a category that occurs frequently, has limited exceptions, and can be measured without rebuilding the entire service desk. The ranking turns prioritization into an evidence-led decision.
Volume alone is an incomplete pilot criterion. Add an estimate of agent time per category, number of approval steps, exception rate, and potential business impact. A request appearing 200 times each month with a straightforward approval path may be a stronger first candidate than one appearing 250 times but requiring several specialized systems. Document why the chosen workflow offers useful measurement with manageable migration risk.
Document Approval Chains and Escalation Paths
For each selected workflow, identify the requester, approver, assigned team, and escalation owner. Record cases where approval is conditional, such as access to a financial application or a request affecting production systems. Resolve unclear ownership before configuring the destination workflow, or the same delays will follow the migration.
Capture what happens when an approver is absent, an employee changes department, or a request is rejected. These paths are often handled through personal relationships in legacy environments and rarely appear in official diagrams. A pilot configured solely around the normal approval route can therefore fail as soon as it meets an exception. Confirm who can reassign work, when escalation occurs, and which actions need a retained audit record.
Phase 2: Pilot One High-Volume Workflow
Choose a contained pilot such as employee software access or a standard device request. Define what enters the new workflow, which historical records are required, and which teams stay on the existing system during the test. Keep rollback criteria and user communication ready before the first live requests arrive.
The pilot should compare records at every stage: submission, approval, assignment, fulfillment, and closure. Review failures as well as successful requests. If a ticket loses its requester identity or an approval rule routes it incorrectly, correct the mapping before increasing volume.
Run the pilot through realistic scenarios rather than a demonstration script. Include missing mandatory fields, duplicate submissions, requests withdrawn after approval, and cases requiring escalation. Record how the new system handles each scenario and which staff member validates the result. Compare the pilot’s outputs with those from the existing workflow so the team can identify defects in data conversion or workflow logic.
Agree on exit criteria before launch. Those criteria might include complete approval history, correct assignment of sampled cases, accurate SLA timers, and successful retrieval of required attachments. If a critical criterion fails, keep the original workflow available while correcting the configuration.
Choose a Single Department
A department with repeatable requests and a cooperative service owner is a manageable starting point. Confirm the number of users, active agents, request categories, and dependent systems. Collect feedback from those raising requests and those fulfilling them; ease of submission alone is insufficient if agent work becomes slower.
Set Baseline SLA Targets
Document the current response and resolution targets, calendar rules, and escalation thresholds. Compare pilot results against this baseline using the same definitions. Track reopened cases and misrouted tickets as well as SLA attainment so a faster average response cannot conceal poorer record quality.
Take care with comparisons between departments. Some service desks measure time only during staffed hours, while others use continuous clocks. Holiday calendars and pause reasons can change reported performance. Validate the timer rules against a small set of known tickets, including one submitted outside business hours. The baseline becomes credible when managers can explain the calculation and reproduce it from individual records.
Phase 3: Connect Assets, Monitoring, and the Service Desk
Once the pilot is reliable, connect incident records to the equipment and services they concern. Decide which system owns asset identity, location, assigned user, and configuration relationships. Test data exchanges with a controlled set of devices before connecting larger inventories.
A monitoring alert should reach a ticket with the correct service and incident ownership, rather than produce a second unrelated record. Likewise, an asset reassignment should update the fields the service desk needs during a future incident. Consistent lifecycle records, as described in asset management in Malaysia, help service teams confirm equipment ownership during incidents and employee moves.
Test failed connections as carefully as successful transfers. Duplicate records, missing permissions, delayed synchronization, or conflicting timestamps should appear in an exception queue with assigned ownership. Record how the team will detect and recover from those failures after the pilot ends.
Define the direction of each data connection. Asset ownership might originate in an inventory system, while incident priority is maintained in service management and event severity remains in monitoring. If every system can overwrite the same field, synchronization problems may be mistaken for user errors. Record the authoritative source for each shared attribute and check that error messages identify the record involved.
During cutover, teams should verify that active incidents retain their existing ownership and that incoming alerts create neither missing nor duplicate cases. Compare a sample of source and destination records each day until volumes and routing have stabilized.
Phase 4: Scale Self-Service and Reporting
Expand from the pilot to additional departments only when record quality, routing, and escalation performance meet agreed criteria. Publish common requests through a service catalog, review the articles users rely on, and simplify forms that generate avoidable follow-up questions. Service owners should approve new request types before they enter the catalog.
Build reporting around service outcomes rather than the number of features deployed. Track request completion times, SLA attainment, repeat incidents, employee satisfaction, and avoidable manual effort. Review results separately for headquarters, branches, and major business units to see where the new operating model needs refinement.
Self-service adoption requires monitoring of the requests users abandon. A form with many fields may reduce bad submissions but cause employees to return to email. Track completed submissions, drop-offs, reopened cases, and requests transferred to agents after portal submission. Improve the least usable workflows before expanding the catalog.
Reporting governance should identify who can amend SLA targets, approve new categories, and interpret department-level results. Without agreed definitions, local teams may create labels that fragment enterprise reporting again. Schedule data quality checks after each rollout phase, including comparisons between service records and their linked assets.
Replace, Upgrade, or Integrate: Choosing Your Modernization Path
Replacing a Legacy Service Desk
Replacement makes sense when the current product cannot meet data, workflow, integration, or governance requirements without extensive workarounds. It offers an opportunity to simplify ticket categories and retire obsolete approval rules. The trade-off is migration effort: data extraction, testing, retraining, integration changes, and cutover planning. A sample migration should confirm what can be retained before the decision is finalized.
Replacement is also a chance to simplify legacy request catalogs. Before transferring hundreds of forms, examine which entries are still used and which reproduce another request under a different name. Retire obsolete workflows through service-owner approval and preserve the historical data required for investigation. A phased switch can then move one department at a time while the old environment remains available for agreed exceptions.
Upgrading In Place
An in-place upgrade is worth considering when the present product has a viable current version, and the organization already has dependable integrations. Configuration updates may resolve delays at lower transition risk. However, leaders should test if the newer version removes the original constraints or merely changes the interface around them. Vendor roadmaps and upgrade dependencies should be recorded in the business case.
An upgrade can still require substantial validation. Test custom fields, integrations, permissions, reporting exports, and approval logic against the new version, especially if older extensions are being retired. The organization should also account for the maintenance window and staff training. Remaining on the existing product makes sense only when its future versions address the operational issues revealed in the initial audit.
Integrating With Existing Tools
Integration can extend the life of an established ticket system when the main problem is missing context from monitoring, assets, or identity services. The team can focus first on a small number of high-value connections. Long-term connector maintenance, data ownership, and exception handling need clear budgets. An integration project is weaker when it creates several copies of the same service record with unclear responsibility for corrections.
Generic Criteria for Any Modern Platform
Compare candidates using a vendor-neutral checklist before demos begin:
- Can the organization export tickets, attachments, approvals, and audit history in usable formats?
- Are roles, field permissions, and data retention rules configurable for existing governance requirements?
- Can records exchange information with current identity, monitoring, and asset systems?
- Do SLA calendars reflect the operating hours of departments and regional teams?
- Can a pilot run alongside existing workflows and be rolled back if validation fails?
- How are integrations, upgrades, data ownership, and exit requirements handled contractually?
The ITSM tool evaluation checklist can be used to compare candidate systems against documented workflow, governance, and integration requirements.
What ITSM Modernization Costs and Where the ROI Comes From
Estimate the full cost before comparing products. Licensing is only one line item. Migration work may involve data preparation, attachment conversion, workflow design, testing, integration changes, agent training, temporary parallel operation, and early-life issue handling. Use an agreed planning period for every option so recurring administration and one-time migration charges are measured on the same basis.
Where Savings Come From
Savings depend on which recurring tasks actually change. Self-service may reduce manual intake for routine requests. Clear approval ownership can shorten waiting time. Connected asset and ticket records can reduce repeated lookup work during diagnosis. Consistent SLA definitions may lower the labor required to assemble monthly reports.
CIOs can quantify these effects by multiplying the current monthly volume of an activity by the minutes spent on it and the relevant labor cost, then comparing the same workload after the pilot. Use conservative assumptions and separate saved agent time from cash savings; time recovered may be redeployed instead of reducing payroll. A sound estimate of ITSM migration cost should compare switching expenses with the ongoing labor and maintenance associated with fragmented workflows.
For instance, if an approval sequence consumes several manual reminders each week, record the average time spent chasing those approvals before the pilot. Once the new workflow is operating, measure the same activity using actual cases, including exceptions. Apply the observed difference to the relevant monthly request volume rather than assuming every request will be automated. Maintain a separate estimate for avoided service disruption, since its value depends on business impact and the reliability of incident data.
Where Budgets Usually Go Wrong
Projects exceed estimates when teams transfer every historical record, reproduce outdated workflows, or discover missing integrations during cutover. Training budgets can also be underestimated if departments use different request and escalation conventions. Another common gap is treating the initial go-live date as the end of the project, with no funds for record checks and incident handling during early operation.
Budget reviews should therefore separate mandatory migration work from optional enhancements, assign owners to data cleanup, and define approval gates before each rollout phase. Where local MYR pricing is required, obtain current vendor quotes with the expected number of agents and requested deployment model; avoid using generic market estimates as a procurement figure.
Frequently Asked Questions
What is ITSM modernization?
ITSM modernization is the improvement or replacement of service management workflows, records, governance, and systems used to handle IT incidents and requests. It may involve upgrading an existing tool, connecting separate systems, or migrating to a new platform. The purpose is to improve how services are managed and measured.
How long does modernization take for a Malaysian enterprise?
The timeline depends on ticket and asset volume, integration requirements, data quality, security review, and the number of departments involved. A single-workflow pilot can be planned before a wider rollout, while complex migrations require deeper testing and staged cutovers. Set dates only after auditing the source records and critical dependencies.
Is ITSM modernization only for large enterprises?
No. Smaller organizations can experience the same duplicate records, delayed approvals, and weak reporting as large enterprises. The scope should reflect the team’s workload and the services that carry business risk. A narrow pilot may deliver better evidence than a broad replacement project.
Where should a small IT team start?
Start by reviewing the last few months of tickets and identifying one repeatable request type that consumes disproportionate effort. Document its owners and approval path, establish the current resolution baseline, and test a simpler workflow with a limited user group. Expand only after the results remain consistent.
Next Steps for Malaysian IT Leaders
Compare Platforms
Use the roadmap to define the workflows, data checks, integration needs, and governance requirements that matter to your organization. Then compare shortlisted solutions against those criteria. Explore our ITSM platform for Malaysian enterprises alongside other candidates and request a demonstration based on a real service workflow from your environment.